Should I Give Money to Someone Asking for Help? Why I Built Mehr
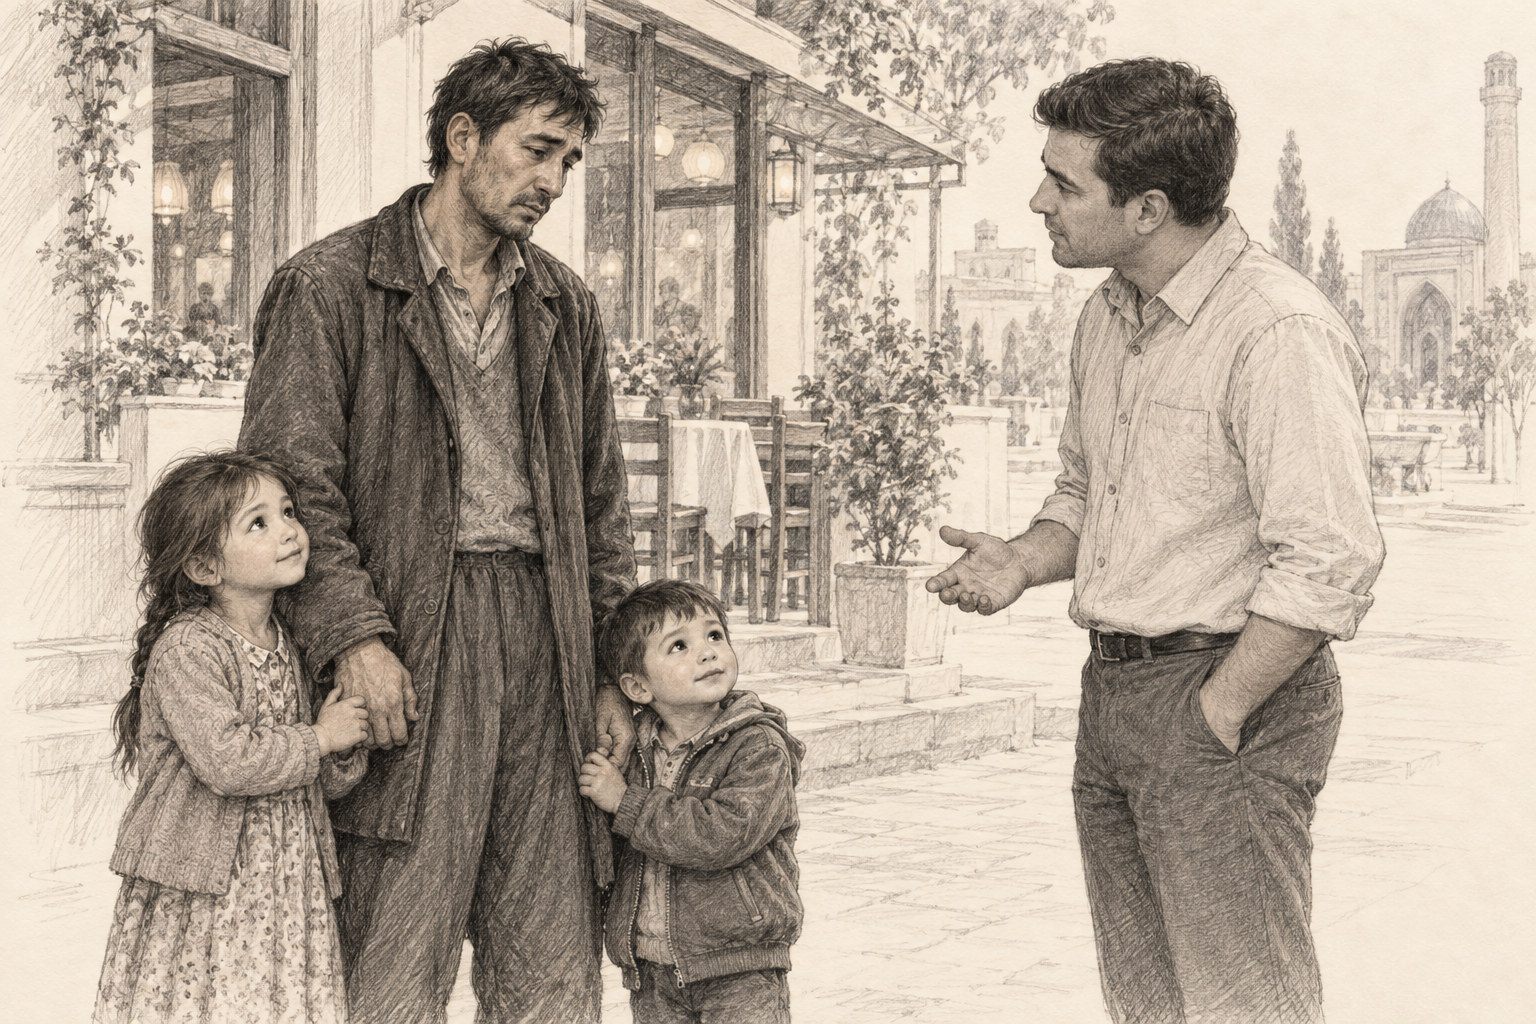
During a lunch break in Tashkent, a request for food left me with a question I could not easily answer: how can I help someone responsibly when I do not know whether their story is true?
The encounter that stayed with me
I had stepped away from work to go to a restaurant. A man stopped me. He was with his very young daughter, and he told me that his family was hungry and did not have enough money for food.
My first instinct was to help, as it usually is. Seeing a child made that feeling stronger. But I also felt the uncertainty that many people recognize in these situations. Was the request genuine? Would money help? Should I buy food, give a smaller amount, or walk away?
I kept returning to the two possible mistakes. If I gave $10 for a fabricated request, I would lose $10. If I refused a genuine request and no one else helped, a child might remain hungry. For me, those consequences carry different weights.
I imagined an extreme case: what if I suspected that a request had a 90% chance of being false? That would still leave uncertainty about genuine need. The percentages were a thought experiment, not evidence about the father I met. A high suspicion, by itself, did not answer how much help would be useful or how strongly I valued avoiding the other mistake.
I began building Mehr to make that reasoning more explicit. I wanted a tool that could take a few understandable answers and return a practical next step, while making its evidence and assumptions available to anyone who wanted to look closer.
What is Mehr?
Mehr helps compare what you could do in a specific encounter: buy agreed food, pay for an agreed essential, offer a useful cash contribution, ask for more information, or keep your money. It can suggest an amount, rather than simply saying “give a little.”
The calculation combines the checked cost, your spending limit, an expressed personal tradeoff, and scenarios for need, a false request, and successful help. It also tests how the recommendation changes when uncertain assumptions change.
The current version is research-informed and experimental. Its short questionnaire and final recommendations have not been validated against real street encounters. That distinction matters whenever a result looks precise.
How to use it, step by step
- Choose the place and describe the request. Is the person asking for food, another essential, cash, or something unclear? Request wording is optional; you can start with an imagined situation.
- Separate a story from a checked fact. Seeing a price or a bill confirms a cost. It does not establish whether the person can afford it. Knowing the situation and checking the need is a different answer; Mehr conditions on your report rather than independently verifying it.
- Set a limit for this encounter. Protect your food, rent, bills, savings commitments, and other essentials first. For example, you might have 1,000,000 UZS left after bills but feel comfortable using only 50,000 UZS for this request. Enter 50,000 UZS. This is not all your remaining income and not a test of generosity.
- Check the help and its price. Enter the actual item or bill total when you know it, or use a dated named food-price example where one is available. Confirm whether direct help is agreed and whether a smaller contribution would actually be useful. If the purpose, agreement, or price is missing, the next step may be to check it.
- Answer four hypothetical choices. An imagined fund can either give you a stated amount or provide the agreed help successfully. Choose what you would actually prefer today, then review your answers. Nothing is paid by answering.
- Read the suggestion and open Evidence. The simple result is a next step. The evidence view shows source links, dates, assumptions, alternative actions, the mathematics, and sensitivity to uncertainty. You can change an assumption and recalculate; changing a number does not turn it into a measured fact.
What evidence and information are behind it?
I assembled several kinds of information, each with a different role. They are not equally reliable, and they are not all inputs to the numerical ranking.
| Information | Where it comes from | How Mehr uses it |
|---|---|---|
| Food insecurity, poverty, and healthy-diet affordability | FAO and World Bank indicators | Population context and an explicitly uncalibrated starting scenario for need. These do not identify a stranger’s need or honesty. |
| Healthy-diet cost | World Bank / FAO Food Prices for Nutrition | A national food-basket benchmark. It is not a prepared restaurant meal price or a monetary measure of suffering. |
| Specific food prices | Named vendor menus and dated saved examples, currently including Tashkent and Tokyo | A possible quote for a named item. Your checked current shop price or actual bill is more relevant to your encounter. |
| Inflation and local consumer-spending figures | World Bank and Uzbekistan’s official statistics services, where available | Inflation helps set a declared price-stress range; spending figures give context. They do not automatically forecast a menu price. |
| Population, urbanization, GDP, and trade | World Bank development indicators | Background economic context. These fields are not all weighted predictors of the recommendation. |
| Official fraud reports and local accounts | Selected public institutional sources and reports in English and local languages | Practical checks and qualitative context. General fraud-crime counts lack a denominator of comparable help requests. |
| Public online text | Bounded news searches, public Bluesky posts, selected public Telegram pages, and search-indexed Reddit titles | Deduplicated topics and exploratory wording analysis. These texts have zero numerical weight in the need and fraud scenarios. |
FAO distinguishes access to food, access to dietary energy, and food consumption. Food Prices for Nutrition measures the cost and affordability of diets using food prices and expenditure information. These are useful population measurements, but they answer different questions from “Does this person need this meal now?” [1] [2]
The app attempts source refreshes where supported and retains dated saved observations when fresh access fails. A retrieval today can still return a statistic from an earlier year. The evidence view distinguishes observation dates, retrieval status, and missing information.
Local context can change affordability and feasible help. Amounts in the main calculation use the selected local currency. The country-comparison examples use stated reference conversion rates, not a continuously updating currency forecast. Purchasing-power-parity figures are economic context, not spendable dollars.
What about scam risk and sentiment analysis?
Mehr does not currently have a calibrated local probability that a particular street request is false. This remains unknown where there is no representative sample of comparable requests with independently checked outcomes.
I reviewed research on crowdfunding fraud, but an online medical-campaign dataset is a different population from a father asking for food in Tashkent. Its fraud figures cannot simply become a local street-request rate. The app does not use that literature’s approximate rate as an automatic country default. [8]
When no measured rate is available, the engine uses 50% as a working midpoint and tests the full 0–100% range. That does not mean half of requests are fraudulent, that countries have equal real risks, or that the range is a statistical confidence interval.
The public-text work is deliberately narrower than a citywide social survey. The current searches collect small accessible samples, including headlines or indexed Reddit titles; they do not continuously read every local group or all Reddit comments. City keywords do not verify a post’s location. Selected historical reports are distinguished from fresh results, and unavailable searches are recorded.
Sentiment analysis summarizes positive, negative, or mixed wording. English analysis uses a simplified VADER-derived lexicon and negation rules; other supported languages use small exploratory lexicons. These adaptations have not been locally validated, and they can misunderstand wording. VADER is a sentiment method, not an honesty test. [7]
A frightening story, a complaint about a scam, or an emotional request is not an independently verified fraudulent encounter. AAPOR’s methods report and research in Nature explain why selected online samples cannot be made representative merely by collecting more of them. In Mehr, sentiment and public-post allegations do not numerically change need, fraud risk, delivery, cost, or personal value. [5] [6]
Culture is handled through practical choices such as asking first, offering privately, and respecting the recipient’s preference. Refusing one food or preferring cash is not automatically treated as proof of deception. Nationality, emotional tone, and appearance are not honesty scores.
How do four questions enter the model?
I did not want to ask people whether they are kind. Instead, the short exercise asks them to choose between a concrete benefit for themselves and a concrete benefit for another person. Research on social preferences uses allocation choices to study tradeoffs; that research informs the approach, but does not validate this particular four-question adaptation. [3]
For the practice questions only, the agreed help is assumed genuine and successful. That keeps the expressed preference separate from uncertainty, which enters the final calculation later.
Computationally, the exercise starts with a working range from zero to four times the fixed practice cost. A choice of help raises the lower bound; a choice of money lowers the upper bound. Four adaptive choices narrow that range, and its midpoint becomes a personal decision weight, W.
For example, with a $10 practice cost, the choices help, money, help, money produce a working interval of $25 to $27.50 and a midpoint W of $26.25. This is the model’s money-equivalent weight for the agreed help. It is not a claim that a person’s hunger is worth $26.25.
The task assumes consistent choices and a simplified money tradeoff. Hypothetical answers can differ from behavior with real money. The app uses neutral options, a realism reminder, and an answer review; making the displayed amounts larger would not, by itself, establish a correction for that bias. [4]
There is also a ceiling in the current exercise. Four all-help answers establish a preference above the last offered amount, not a true upper limit on someone’s concern. The app nevertheless uses its bounded working range. It may underrepresent a person who gives exceptional weight to avoiding a particular harm. That is a limitation of the tool.
The mathematical model: paying and refusing both have costs
The central idea is to compare the expected value of useful help with the cost of providing it, within a hard budget. The variables are:
- B: your spending limit for this request.
- C: the checked total cost of the specified need.
- s: the assumed probability of a materially fabricated request.
- p: the assumed probability of this unmet need conditional on a nonfabricated request.
- q: the assumed probability of useful delivery conditional on genuine need and a nonfabricated request.
- W: your expressed personal decision weight from the practice choices.
- f: any entered extra costs, modeled as a fixed cost of helping.
The model’s probability of a nonfabricated request with genuine need is:
This is a conditional-probability chain, not an assumption that need and fabrication are independent. Neither p nor s is established by the country statistics. On the fabricated branch, the model assumes zero benefit for the specified request; that does not establish that the person has no other needs.
For an agreed direct purchase, the central calculation is:
Ukeep = 0
The engine ranks feasible options by benefit minus cost and chooses a positive value. Keeping money at zero is a normalized comparison baseline; it does not mean refusing genuine need has no consequence.
To see that, let K be the amount paid plus extra costs, and H the model’s value of the proportion of help provided. For a complete direct purchase, H = 1. The same comparison can be expressed as expected losses:
E[Lhelp] = K + gW(1 − qH)
Uhelp = E[Lrefuse] − E[Lhelp]
This represents my original concern: giving may lose money, while refusing may leave an important need unmet. The comparison uses a personal decision-value equivalent. It does not measure the actual damage of hunger, predict days without food, or estimate whether someone else will help later.
How does Mehr suggest a smaller amount?
When you report that a partial contribution would be useful, the cash model uses coverage D = min(A/C, 1), where A is the offered amount. It applies a declared diminishing-return curve:
V = g × q × W
Ucash(A) = V × h(D) − A − f
The unconstrained optimum is V/ln(2) − C. The app clamps it between zero and the smallest applicable cap: the requested amount, the checked need cost, and your budget after extra costs. It then rounds down to two decimal places and checks whether helping still has positive modeled value.
Amax = min(requested amount if given, C, B − f)
The logarithmic curve is this app’s modeling choice, not a measured relationship between money and relief. Research on microgiving informs the broader use of diminishing utility and fixed costs. [9] If a smaller contribution has not been agreed as useful, the engine does not assume that a fraction of the price solves an indivisible need.
Direct help is feasible only when it is agreed and fits your budget, including extra costs. Missing purpose, agreement, cost, or preference answers can lead to a request to check or complete information. Reported contradictions, unsafe situations, and urgent needs take precedence over the ordinary utility ranking.
One scenario, three different suggestions
This example uses the current decision engine. All amounts are in US dollars for illustration; these are not local price observations. Hold the meal cost at $10, the spending limit at $15, W at $26.25, p at 1 because the donor reports checking the need, q at the illustrative 0.85, and extra costs at zero. Direct help is agreed, a partial contribution is useful, and the ordinary central-value mode is selected.
| Assumed false-request risk | Central suggestion | Why the ranking changes |
|---|---|---|
| 10% | Buy the agreed $10 meal | Expected full-help value is about $20.08; benefit exceeds the $10 cost. Full cash has the same value, and this setup breaks the positive tie toward direct help. |
| 60% | Offer $2.87, if that contribution is useful | Full-help value falls to about $8.93. A full $10 purchase has negative modeled value, while the declared partial-help curve gives a small positive value to $2.87. |
| 90% | Keep your money under these assumptions | Full-help value is about $2.23. No positive cash amount improves the modeled comparison. |
These risk values are deliberately assumed, not measured rates for Tashkent or any other place. The table shows how the model responds. It does not establish what happened in my restaurant encounter. If partial help were not useful, the middle row would instead keep the budget under the same assumptions.
What do the 10,000 scenarios mean?
The app runs 10,000 hypothetical scenarios to examine how dependent the ranking is on uncertain inputs. It varies the personal working interval, need, delivery, and price. Without a manual fraud scenario, it also stresses s uniformly across 0–100%. A manually chosen s is held fixed. The suggested cash amount also stays fixed during these tests; it is not re-optimized for every draw.
The default q of 0.85 is illustrative and starts equally for cash and direct help; it is not a locally measured success rate. Delivery is stressed by ±0.10. Price stress starts at ±10%, uses the magnitude of reported inflation if larger, and is capped at ±35%. This is a chosen stress design, not a prediction of future prices.
Where a relevant population indicator π is available, the central need scenario uses it as an uncalibrated proxy. Sensitivity varies a selection-odds multiplier R from 0.1 to 100, log-uniformly, through p = πR/(1 − π + πR). This explores what might change when people asking for help differ from the wider population. Those selection bounds are assumptions, not fitted estimates.
The reported simulation ranges and ranking frequencies describe this chosen model. “Usually the same” means the action repeatedly wins in those scenarios; it does not mean a 90% accurate recommendation. The displayed ranges run from the 5th to the 95th simulated percentiles. The cautious mode uses the 5th-percentile modeled utility and can suggest checking first when uncertainty changes the central advice. Modeled regret and an upper bound on the value of perfect information describe how useful clarification might be within the same assumptions.
What would make the tool stronger?
A defensible country-specific fraud estimate would need a defined population and time period, a representative sample of comparable requests, independently checked need and truthfulness, information about sampling and unresolved outcomes, and evaluation on new encounters. It would need calibration checks and honest uncertainty estimates. More selected comments alone cannot supply that.
The preference task also needs testing against real choices, including whether its fund-allocation framing carries over to spending one’s own money. Partial-help curves and delivery assumptions need empirical validation. Country coverage, source freshness, and accessibility remain areas to improve.
I am sharing Mehr as a transparent early tool, with room for feedback about unclear questions, missing evidence, and suggestions that do not fit real situations.
Try it on the web or your phone
Mehr is free, requires no account, and does not take payments or ask for card details. It supports English, Russian, Persian, Arabic, Korean, Japanese, Uzbek, Turkish, and Chinese.
You can use Mehr directly in your browser or follow the iPhone and Android Home Screen instructions. The current installation option is a web app and requires internet.
Your answers are sent to the app’s server when you request a calculation. The app does not write encounter answers to an app database, and they clear from the open page when you reload; the hosting provider may retain technical logs. Avoid entering identifying details. Read the privacy explanation.
I still want to stop when someone asks for help. What I want from Mehr is a clearer way to decide what I can afford, what might actually help, and which uncertainty I should check next. The person in front of me matters more than an unexplained number on a screen.
Selected sources and research
The sources below support individual measurements, methods, and design choices. They do not validate Mehr as a complete system. The implementation described here was reviewed on 11 October 2026.
- FAO. Measuring hunger, food security and food consumption. Distinct population measures of food access and consumption.
- World Bank / FAO. Food Prices for Nutrition. Diet-cost and affordability methods and data.
- Charness & Rabin (2002). Understanding Social Preferences with Simple Tests. Quarterly Journal of Economics. Allocation-choice research; Mehr’s adaptation is unvalidated.
- Brown, Ajzen & Hrubes (2003). Further tests of entreaties to avoid hypothetical bias in referendum contingent valuation. Journal of Environmental Economics and Management. Evidence relevant to realism reminders.
- AAPOR Task Force (2014). Social Media in Public Opinion Research. Sampling, coverage, and validation considerations.
- Bradley et al. (2021). Unrepresentative big surveys significantly overestimated US vaccine uptake. Nature. Evidence about selection bias, from a different application.
- Hutto & Gilbert (2014). VADER: A Parsimonious Rule-Based Model for Sentiment Analysis of Social Media Text. AAAI ICWSM. Mehr uses a simplified adaptation.
- Perez et al. (2020). I call BS: Fraud Detection in Crowdfunding Campaigns. Crowdfunding research; not a local street-request prevalence study.
- Jiang, Xing, Xu & Zou (2022). Microgiving with Digital Platforms. Working paper; relevant donation-model structure, not validation of Mehr’s log curve.
- Additional local source links and dates are available in Mehr’s Evidence view. Examples include Uzbekistan SIAT registered fraud offenses, Tashkent’s public IIBB channel, Oqtepa Lavash, and Matsuya’s named menu. Availability and prices can change.